Posts tagged "Inference"
5 posts found
LLM Inference: What businesses need to know
Learn what LLM inference is, how it works, how it differs from training, and which hardware and frameworks support it. Read our article now!
Read More →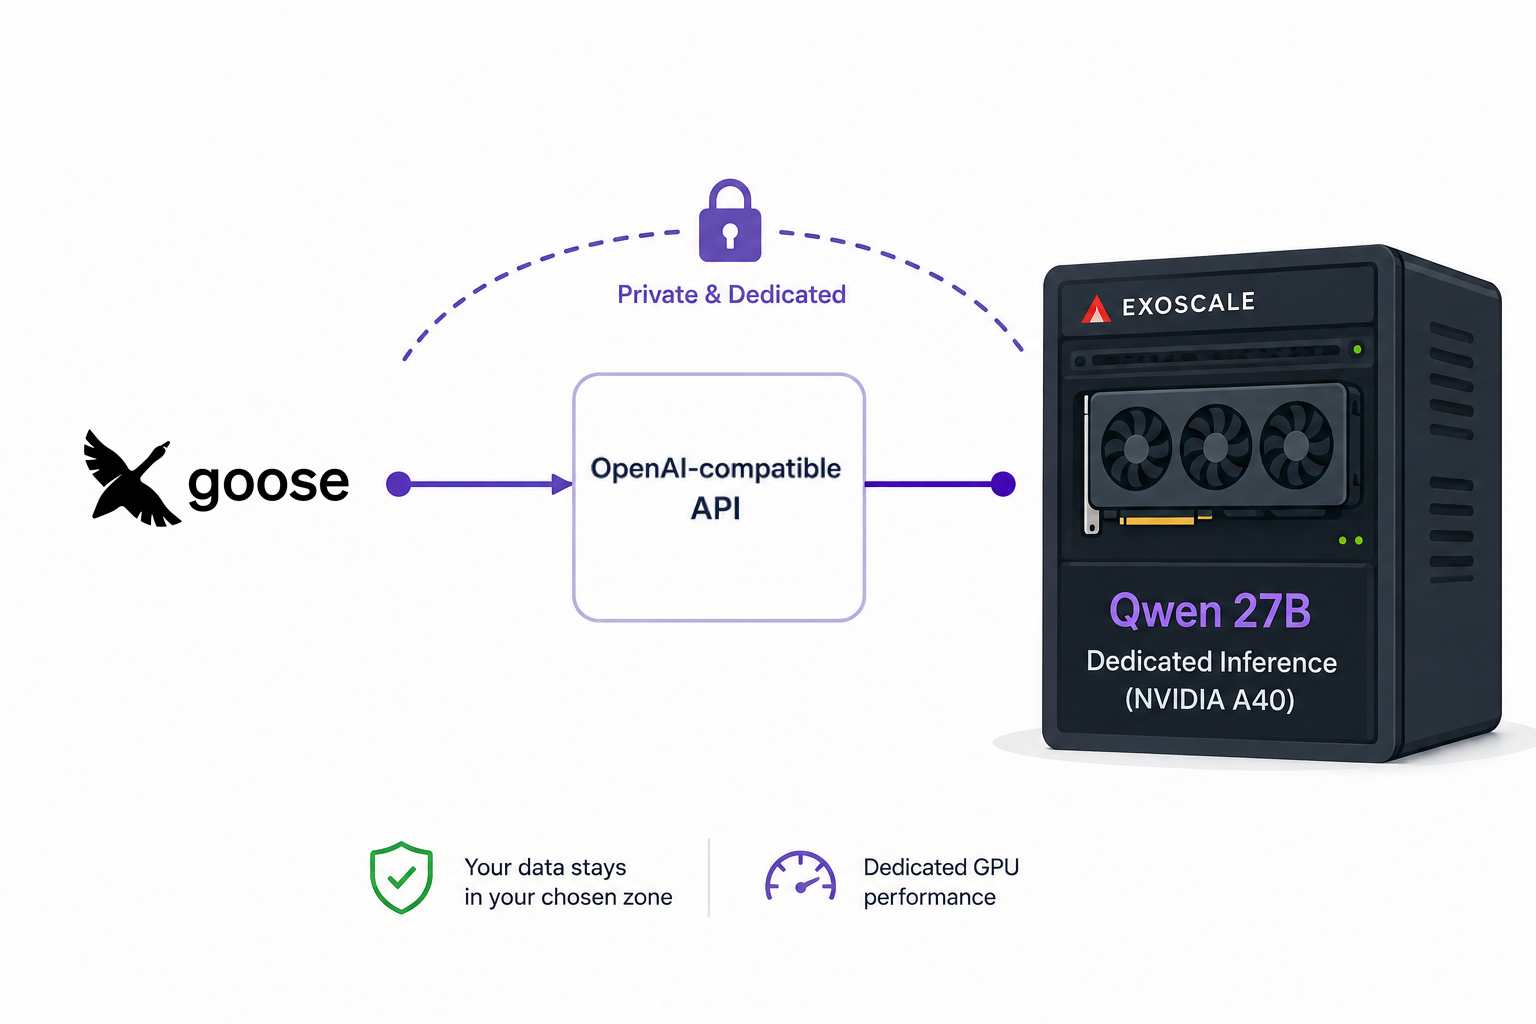
Build a Sovereign Coding Agent with Goose and Exoscale Dedicated Inference
Deploying a simple AI coding agent using Goose and Exoscale Dedicated Inference
Read More →
GPU Partitioning with MIG on Exoscale SKS
GPUs are massively used in the age of AI, but depending on the workload we need to run, a single GPU can sometimes be over-dimensioned.
Imagine deploy...
Read More →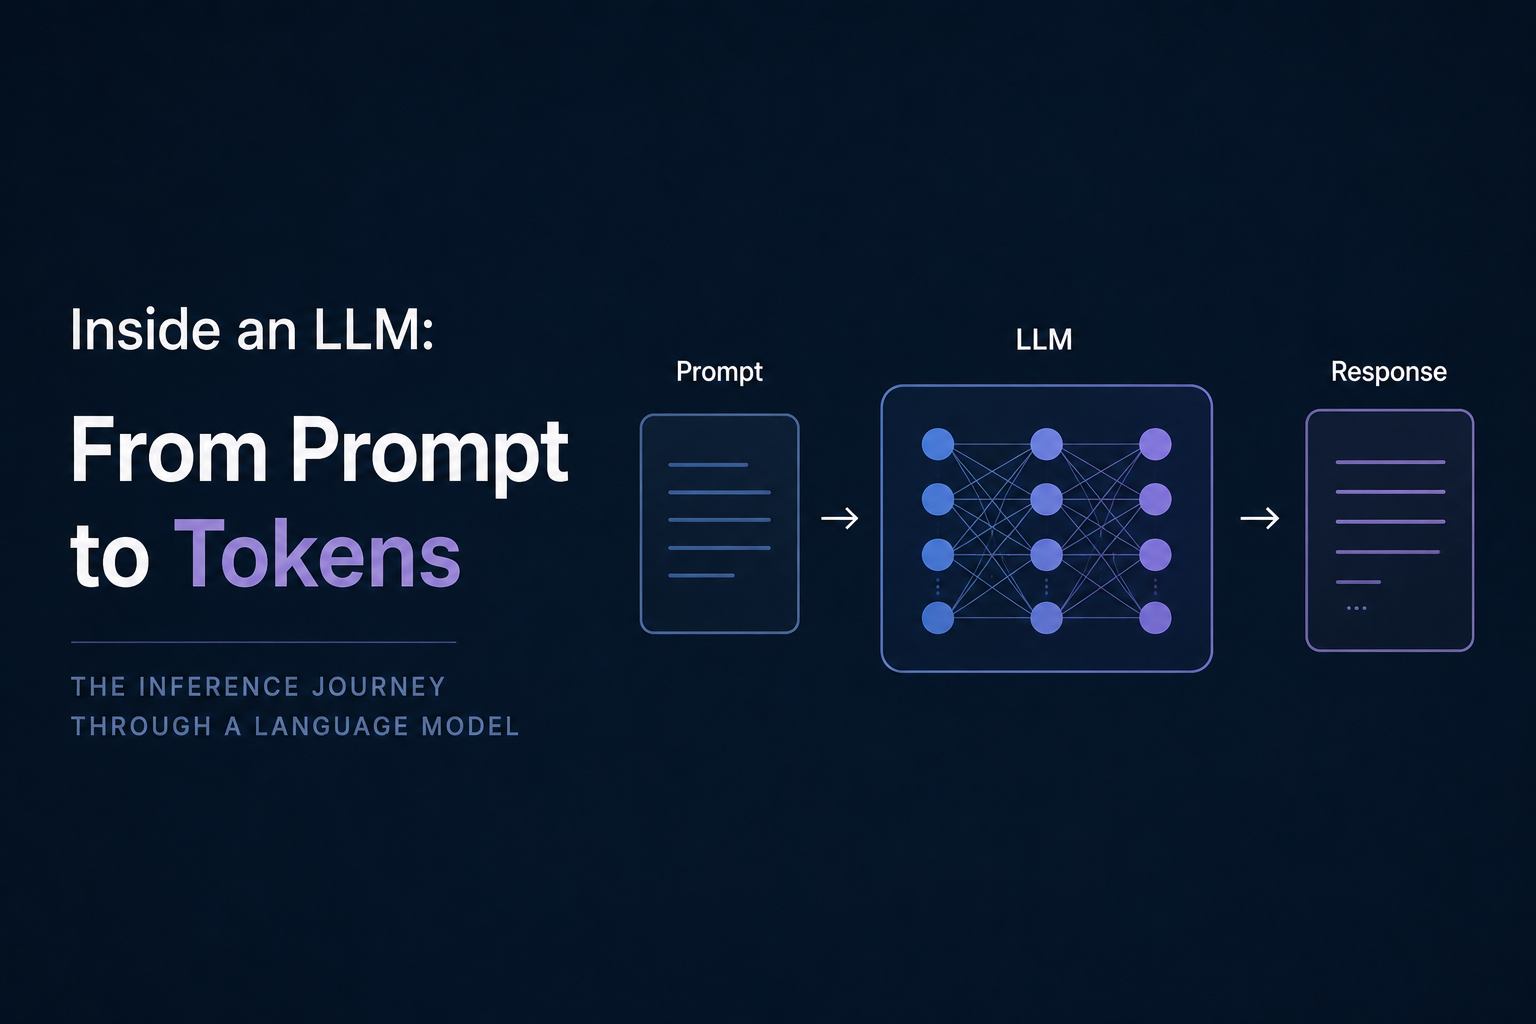
Inside an LLM: From Prompt to Tokens
Learn how LLM inference transforms a prompt into tokens through prefill and decode, hidden states, attention, MLP, KV cache, and transformer layers.
Read More →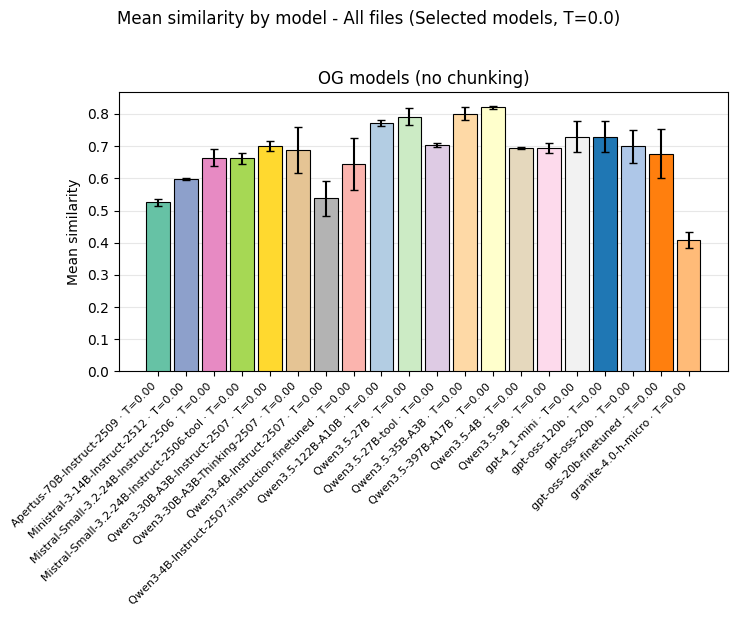
From Commercial API to Sovereign Infrastructure: A Practical Guide to LLM Workload Migration
In January 2026, a software company received a routine notification from their cloud AI provider: the model powering their production pipeline was bei...
Read More →